ResearchExplainer
What is an LLM: how large language models learn, from tokens to RLHF
A large language model predicts the next token, learns from hundreds of billions of them, and is then tuned on human feedback to follow instructions.
Every ClaudeGPT Si story about RLHF, newest first: news, analysis, reviews and guides.
3 stories · Updated
A large language model predicts the next token, learns from hundreds of billions of them, and is then tuned on human feedback to follow instructions.
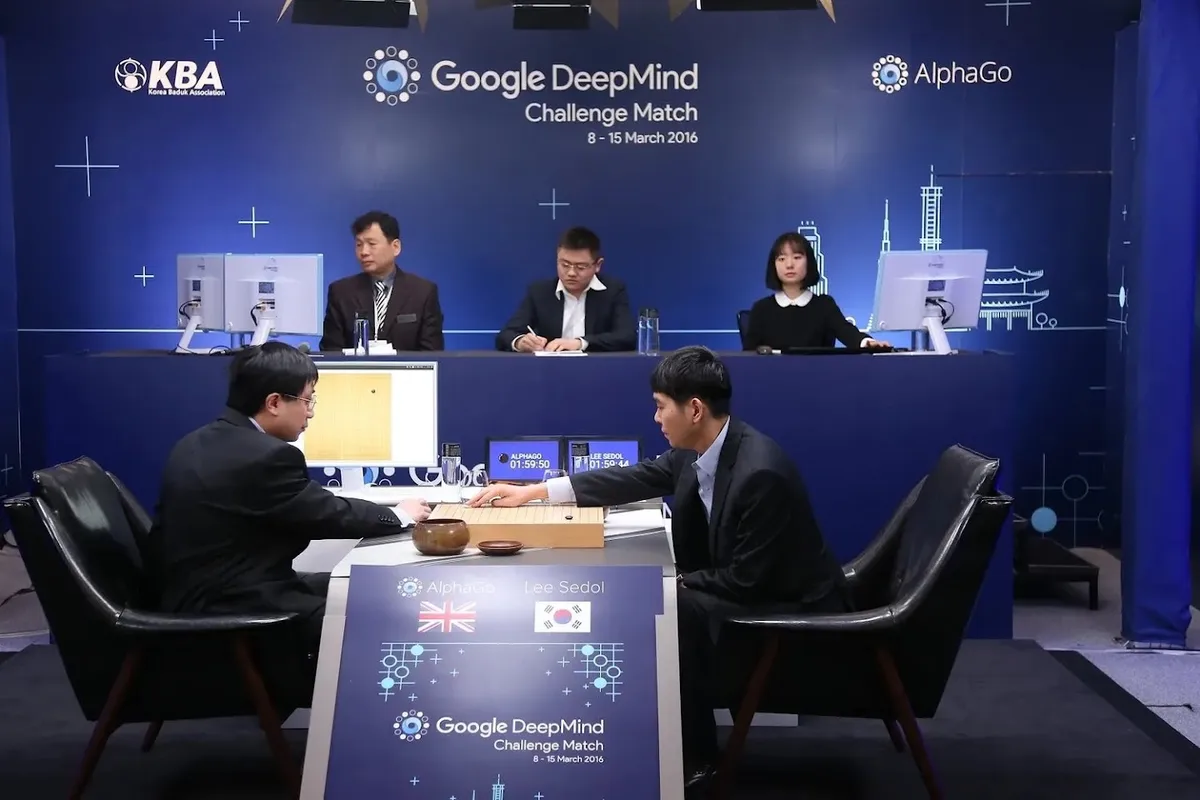
Agents, environments, rewards and policies in plain words, the Atari and AlphaGo results, and how RLHF and verifiable rewards train today's language models.
Reinforcement learning from human feedback turned raw language models into assistants. Here is how it works, where it fails, and how DPO simplifies it.