ResearchExplainer
What is quantization in AI: running LLMs in 8 and 4 bits
Quantization stores a model's weights in fewer bits to cut memory by up to 4x. How INT8, INT4, FP4, GPTQ, AWQ and GGUF work, and what accuracy it costs.
Every ClaudeGPT Si story about Meituan, newest first: news, analysis, reviews and guides.
3 stories · Updated
Quantization stores a model's weights in fewer bits to cut memory by up to 4x. How INT8, INT4, FP4, GPTQ, AWQ and GGUF work, and what accuracy it costs.
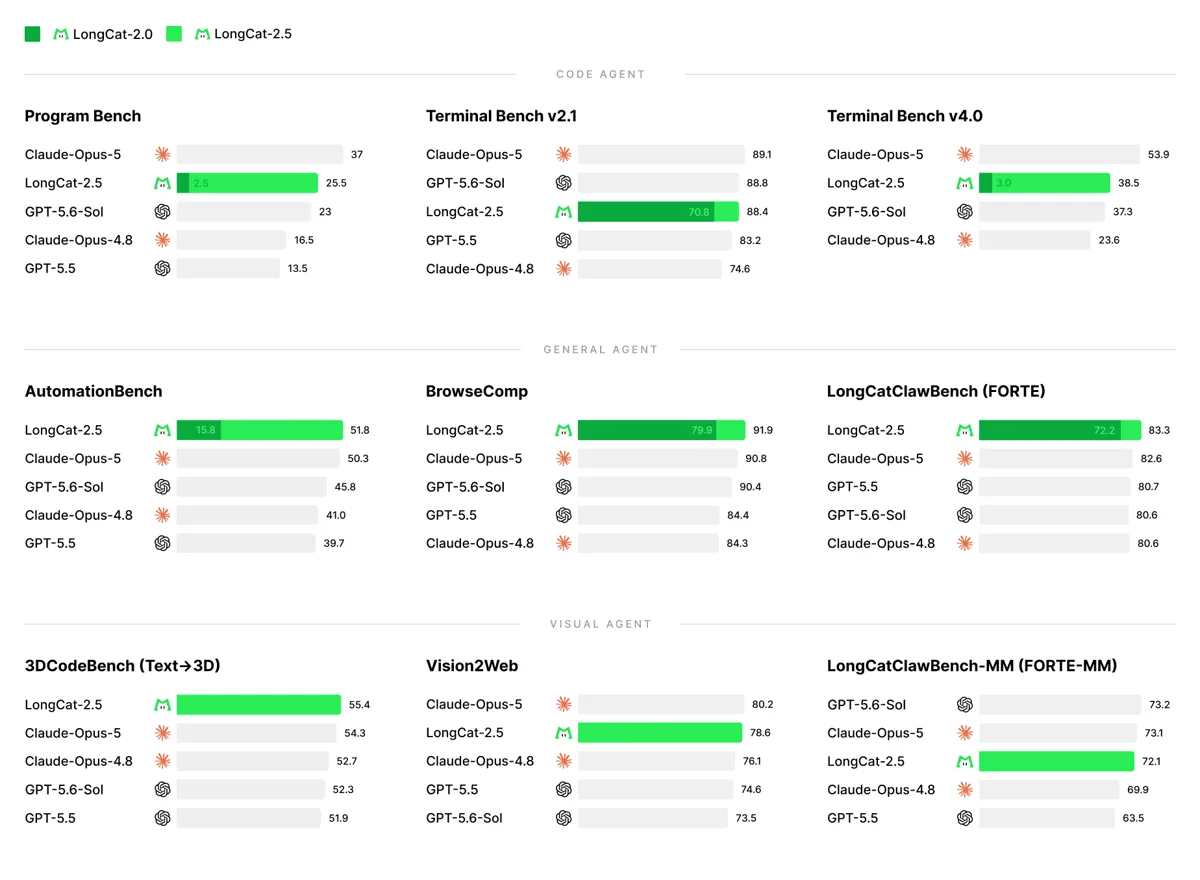
Both are MIT-licensed with 1M-token context, and LongCat's promo price matches DeepSeek's peak rate, but DeepSeek halves it off-peak and its 1017 update leads most coding tests.
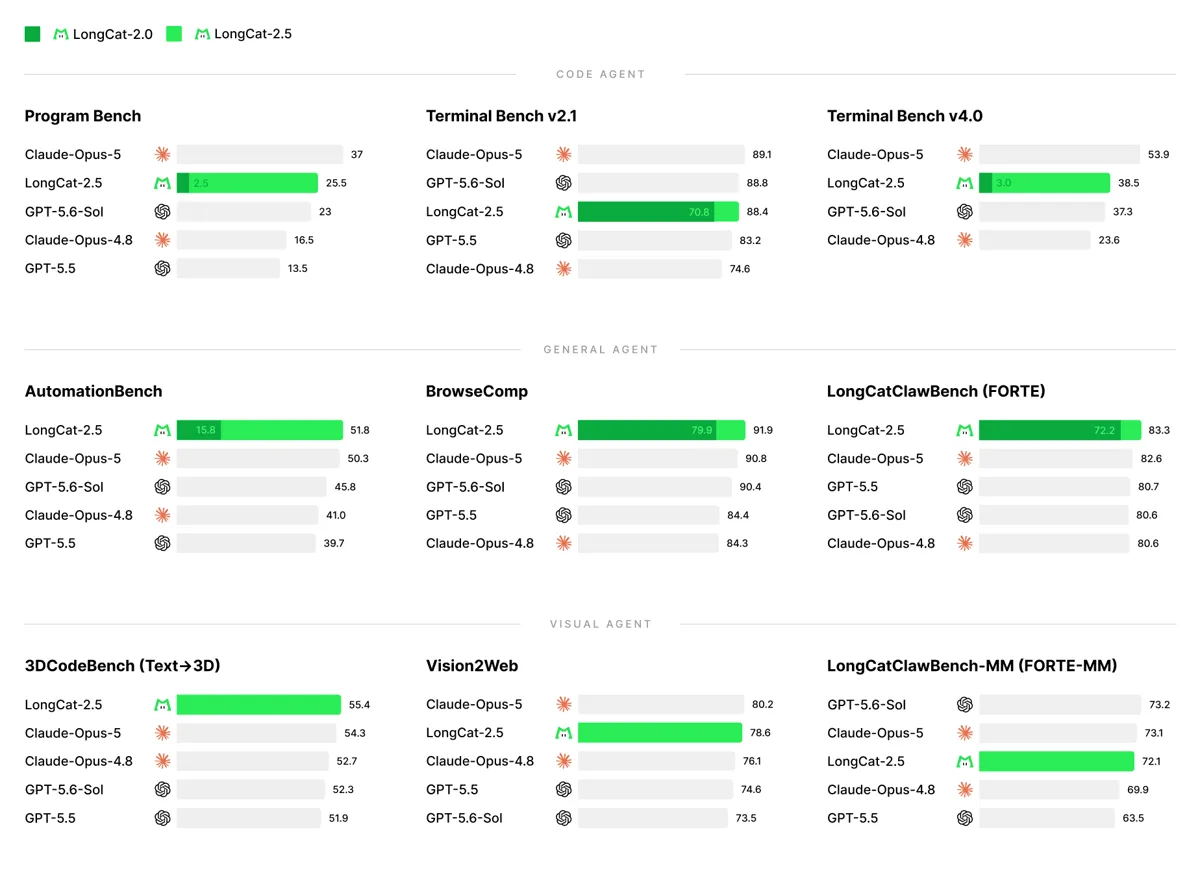
The MIT-licensed model reads 1 million tokens, was trained on Chinese chips, and costs $0.30 per million input tokens on Meituan's API for now.