Key takeaways
- DeepSeek's deepseek-flash costs $0.30 in and $1.20 out per million tokens at peak and half that off-peak, while GLM-5.3-Flash costs $0.15 and $0.50 at all hours.
- All four models have 1M-token context windows; DeepSeek's weights are MIT-licensed, as is GLM-5.3-Flash, but GLM-5.3 has a custom licence with a security-review clause for very large API providers.
- On Artificial Analysis's Intelligence Index v5.0.1, read on November 19, 2026, DeepSeek V4.1 Flash 1017 scores 33 and GLM-5.3 scores 32.
DeepSeek vs GLM comes down to price against licence terms. DeepSeek's V4.1-Flash is cheaper per token with caching and edges GLM-5.3 by one point on Artificial Analysis's independent index. Z.ai's GLM-5.3 family has a flat-fee coding subscription, and its small model, GLM-5.3-Flash, costs about the same as DeepSeek's off-peak rate at any hour. Both labs serve 1M-token context windows and publish open weights. DeepSeek's current models are MIT-licensed. GLM-5.3, Z.ai's flagship, comes with a custom licence. Prices below are from DeepSeek's pricing page and Z.ai's pricing page as of November 19, 2026.
This comparison is based on the products' docs, model cards and published benchmark results. No hands-on testing was done for it.
Which DeepSeek and GLM models are current
DeepSeek's API has two models. deepseek-flash runs DeepSeek-V4.1-Flash-1017, an update released on October 17. deepseek-v4-pro runs DeepSeek-V4-Pro-0813, which became generally available on August 13. The older names deepseek-v4-flash and deepseek-v4-flash-vision-exp still work, but they now route to V4.1-Flash.
Z.ai's current models are GLM-5.3, released on August 18, and GLM-5.3-Flash, released on August 26, according to its release notes.
The lineups pair up like this:
- Small and cheap: DeepSeek V4.1-Flash against GLM-5.3-Flash. Both are mixture-of-experts models, which run only part of their network for each token. V4.1-Flash has a 552B-parameter backbone and activates 8B parameters per token when reading the prompt and 16B when writing, according to its model card. GLM-5.3-Flash has 320B parameters and activates 18B.
- Flagship: DeepSeek V4-Pro against GLM-5.3. DeepSeek lists V4-Pro at 1.6T parameters with 49B active.
DeepSeek vs GLM at a glance
| DeepSeek V4.1-Flash | GLM-5.3-Flash | DeepSeek V4-Pro | GLM-5.3 | |
|---|---|---|---|---|
| API model name | deepseek-flash |
glm-5.3-flash |
deepseek-v4-pro |
glm-5.3 |
| Input, per 1M tokens | $0.30 peak, $0.15 off-peak | $0.15 | $1.32 peak, $0.66 off-peak | $1.40 |
| Cached input, per 1M | $0.006 peak, $0.003 off-peak | $0.03 | $0.044 peak, $0.022 off-peak | $0.26 |
| Output, per 1M tokens | $1.20 peak, $0.60 off-peak | $0.50 | $3.96 peak, $1.98 off-peak | $4.40 |
| Context window | 1M tokens | 1M tokens | 1M tokens | 1M tokens |
| Max output | 384K tokens | 128K tokens | 384K tokens | 128K tokens |
| Image input | Yes | Yes, plus video and files | No | No, text only |
| Weights licence | MIT | MIT | MIT | Custom GLM-5.3 License |
| Size (total / active) | 552B / 8B to 16B | 320B / 18B | 1.6T / 49B | Not published |
Prices read on November 19, 2026. Specs from each lab's docs and model cards.
How much DeepSeek and GLM cost
DeepSeek charges two rates. Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, except Chinese public holidays. Every other hour, weekends included, is off-peak and costs half. Z.ai's API has one price at all hours.
At peak, deepseek-flash costs twice what GLM-5.3-Flash does for input, $0.30 against $0.15 per million tokens, and more for output, $1.20 against $0.50. Off-peak, the input prices match at $0.15, and GLM-5.3-Flash is still cheaper on output, $0.50 against $0.60.
Cached input changes the sums. Agents resend the same long prompt, so most of their input is cache hits. DeepSeek charges $0.006 per million for a cache hit at peak, a fifth of GLM-5.3-Flash's $0.03. Z.ai doesn't charge for storing the cache for now., with no end date given.
The flagships cost about the same. V4-Pro at peak is $1.32 in and $3.96 out, against GLM-5.3's $1.40 and $4.40. Off-peak, V4-Pro costs about half as much as GLM-5.3.
A worked example: an agent run that sends 10M fresh input tokens and gets 1M back costs $4.20 on deepseek-flash at peak, $2.10 off-peak, and $2.00 on GLM-5.3-Flash. The same run costs $17.16 on V4-Pro at peak, $8.58 off-peak, and $18.40 on GLM-5.3. With heavy caching, DeepSeek pulls ahead.
Z.ai also lists two older models as free: GLM-4.7-Flash and GLM-4.5-Flash. DeepSeek has no free API model. It stopped billing for the web searches and page fetches its model makes on its own from November 18. The standalone Search and Fetch APIs cost $0.75 per 1,000 requests. For more providers, see our AI API pricing table.
Coding plans: Z.ai has one, DeepSeek doesn't
Z.ai sells the GLM Coding Plan, a subscription in three tiers: Lite, Pro and Max. Z.ai says it starts at $18 a month but doesn't list the Pro and Max prices on that page. Usage is counted in credits, with a limit every five hours and a weekly limit:
| GLM Coding Plan | Credits per 5 hours | Credits per week |
|---|---|---|
| Lite | 2,000 | 10,000 |
| Pro | 12,000 | 60,000 |
| Max | 28,000 | 140,000 |
Every tier includes GLM-5.3 and GLM-5.3-Flash. A GLM-5.3 call uses about three times as many credits per token as a GLM-5.3-Flash call. Z.ai estimates that with 95% of input coming from cache, Lite covers 48M to 97M GLM-5.3 tokens a week and Pro covers 290M to 580M, depending on how much runs off-peak. Requests for GLM-5.2 or GLM-5.1 go to GLM-5.3. Usage outside 14:00 to 18:00 Singapore time on weekdays costs half the credits. The plan works in Claude Code, Codex, OpenCode, Cline, OpenClaw and Z.ai's own ZCode.
DeepSeek's docs list no subscription. You pay per token. The API has an Anthropic-format endpoint and an OpenAI Responses endpoint, so it plugs into the same tools, and the docs have setup guides for Claude Code, Codex, OpenCode and OpenClaw. DeepSeek also has its own agent, DeepSeek Harness, in developer preview.
If you code with an agent every day, the GLM plan is easier to budget. If you use one now and then, DeepSeek's off-peak rates cost less.
Open weights and licences
Both labs post weights on Hugging Face. DeepSeek's V4.1-Flash-1017 and V4-Pro-0813 are under the MIT License, which lets anyone use, change and sell them.
GLM-5.3-Flash is also MIT. GLM-5.3 is not. Its licence reads like MIT with one addition. A company that sells a model-as-a-service business, meaning API access to a model, and whose group earns more than $10 billion over any 12 months must pass a Z.ai security review before using GLM-5.3 commercially. That clause covers only a handful of companies, but it means GLM-5.3 isn't under a standard open-source licence. More on that in our guide to GLM-5.3's licence.
Running any of these takes data-center hardware: DeepSeek's example serves V4-Pro on four GB300 GPUs. See how to run GLM-5.3 locally for the GLM side.
What the benchmarks show
Each lab put the other's model in its own benchmark table. Those numbers are the companies' own, with harnesses and settings each chose.
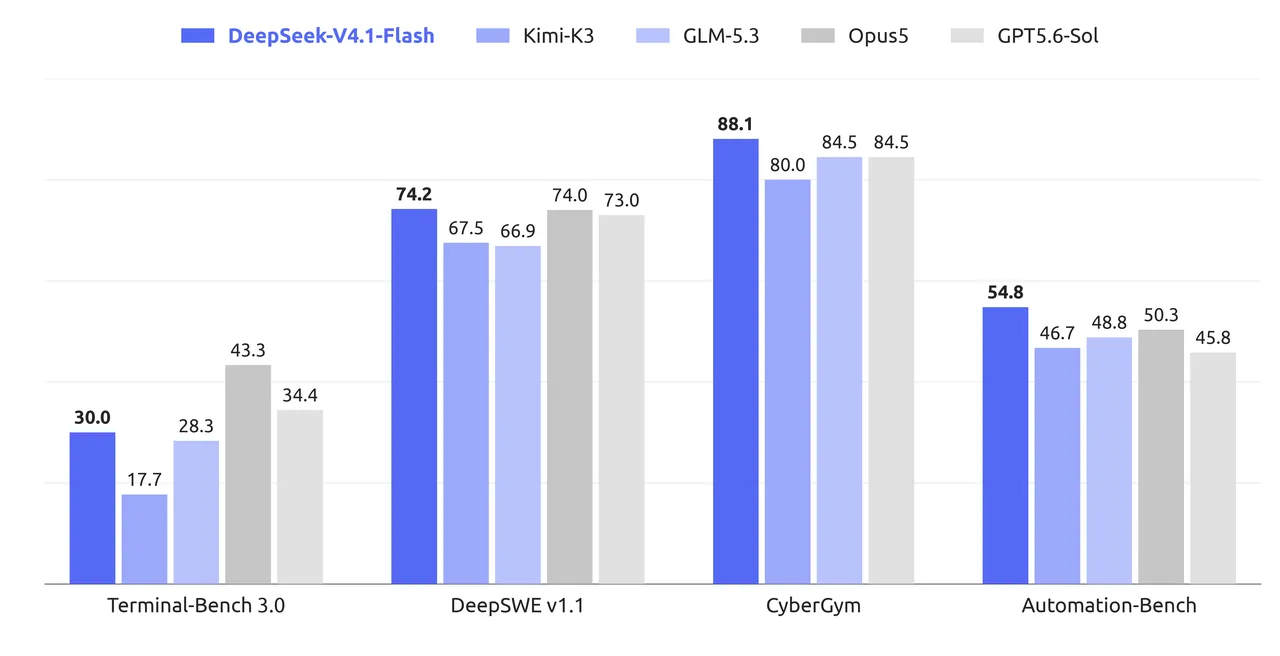
DeepSeek's V4.1-Flash-1017 model card compares its small model with Z.ai's flagship:
| Benchmark (DeepSeek's table) | DeepSeek V4.1-Flash-1017 | GLM-5.3 |
|---|---|---|
| Terminal-Bench 4.0 | 42.3 | 37.9 |
| DeepSWE v1.1 | 77.0 | 66.9 |
| NL2Repo-Bench | 68.2 | 58.0 |
| ProgramBench | 29.1 | 19.0 |
| Agents' Last Exam | 35.4 | 28.5 |
| Apex Bench v1.1 | 72.1 | 56.6 |
Z.ai's GLM-5.3 model card compares its flagship with DeepSeek's:
| Benchmark (Z.ai's table) | GLM-5.3 | DeepSeek V4-Pro-0813 |
|---|---|---|
| Terminal Bench 2.1 | 88.2 | 87.9 |
| DeepSWE v1.1 | 66.9 | 62.7 |
| NL2Repo | 58.0 | 61.1 |
| CyberGym | 84.5 | 83.3 |
| Toolathlon Verified | 73.0 | 74.1 |
| Agents' Last Exam (CLI) | 28.5 | 25.7 |
| HLE with tools | 62.5 | 60.0 |
| GDPval-AA v2 | 1769 | 1590 |
DeepSeek shows its cheaper Flash model well ahead of GLM-5.3. Z.ai shows GLM-5.3 slightly ahead of DeepSeek's Pro model. Z.ai's table doesn't include V4.1-Flash-1017, which came out two months after GLM-5.3.
Independent numbers
Artificial Analysis puts the two close together. On its Intelligence Index v5.0.1, read on November 19, 2026, DeepSeek V4.1 Flash 1017 at max effort scores 33 and GLM-5.3 at max effort scores 32. It measured V4.1-Flash at 169 output tokens per second and GLM-5.3 at 83. V4-Pro and GLM-5.3-Flash weren't on that page. The top open-weights model there, Kimi K3.1 Pro, scores 46.
OpenRouter's rankings, with usage data through November 18, 2026, show where developers send traffic. DeepSeek V4.1 Flash 1017 was the most-used model that week at 62.1 trillion tokens. The earlier V4.1 Flash ranked third at 16 trillion. GLM 5.3 Flash ranked fifth at 10.9 trillion.
DeepSeek and GLM apps
Both labs have a consumer chatbot. DeepSeek's web app and mobile app run V4.1-Flash-1017, and V4-Pro is available there as "Expert Mode". Z.ai's chat at chat.z.ai says it runs on GLM-5.3-Flash. Neither page lists a price for the chat.
Which to pick
For the lowest token bill, an agent that resends long cached prompts, or work you can schedule outside DeepSeek's peak hours, DeepSeek V4.1-Flash is the better buy. It also leads the independent index by a point and generates text twice as fast as GLM-5.3. If you want a fixed monthly price in Claude Code or another coding agent, GLM's plan is the one on offer. GLM-5.3-Flash also takes video input and costs less than DeepSeek's peak rate. For self-hosting at a very large company, check GLM-5.3's licence first. Everything from DeepSeek is MIT.
DeepSeek ships often: the October 17 Flash update came five weeks after V4.1-Flash launched on September 10. Check the V4.1-Flash explainer and DeepSeek vs Kimi for how it stacks up elsewhere.
Frequently asked questions
Is GLM-5.3 better than DeepSeek?
It depends on whose numbers you read. Z.ai's tables show GLM-5.3 slightly ahead of DeepSeek V4-Pro-0813 on most tests, while DeepSeek's tables show V4.1-Flash-1017 ahead of GLM-5.3. Artificial Analysis scores them 33 for DeepSeek V4.1 Flash 1017 and 32 for GLM-5.3.
Is GLM cheaper than DeepSeek?
GLM-5.3-Flash is cheaper than deepseek-flash at peak hours and on output tokens, at $0.15 in and $0.50 out per million. DeepSeek is cheaper off-peak for cached input, and V4-Pro off-peak costs about half as much as GLM-5.3.
Does DeepSeek have a coding plan like GLM?
No. DeepSeek's docs list only pay-per-token API pricing, though the API works in Claude Code, Codex and OpenCode. Z.ai's GLM Coding Plan has Lite, Pro and Max tiers starting at $18 a month.
Are DeepSeek and GLM open source?
Both publish open weights. DeepSeek V4.1-Flash, V4-Pro and GLM-5.3-Flash are under the MIT License, while GLM-5.3 uses a custom licence that requires a Z.ai security review for API providers with more than $10 billion in yearly revenue.
Sources
- Models & PricingDeepSeek
- Change LogDeepSeek
- DeepSeek-V4-Pro GA ReleaseDeepSeek
- DeepSeek-V4.1-Flash-1017 model cardDeepSeek
- DeepSeek-V4.1-Flash model cardDeepSeek
- DeepSeek-V4-Pro-0813 model cardDeepSeek
- PricingZ.ai
- Release notesZ.ai
- GLM-5.3Z.ai
- GLM-5.3-Flash/FlashXZ.ai
- GLM Coding Plan overviewZ.ai
- GLM-5.3 model cardZ.ai
- GLM-5.3 LicenseZ.ai
- GLM-5.3-Flash model cardZ.ai
- Open weights modelsArtificial Analysis
- LLM rankingsOpenRouter